Publications
Conference papers and preprints. Each entry has a short summary of the key idea; click an illustration to enlarge it.
Conference Papers
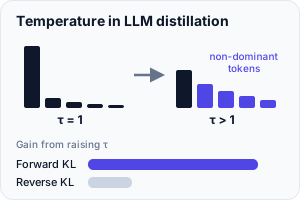
- Rethinking the Role of Temperature in Large Language Model DistillationIn Conference on Empirical Methods in Natural Language Processing (EMNLP), Main Conference, Short Paper, 2026Key idea The common verdict that reverse KL beats forward KL for LLM distillation was measured at temperature 1. We show that temperature injects signal from non-dominant tokens into forward KL but mostly just rescales reverse-KL gradients. With a well-chosen temperature, forward KL overtakes reverse KL, and simple KL objectives gain up to +6.6 ROUGE-L, competitive with recent state-of-the-art methods.
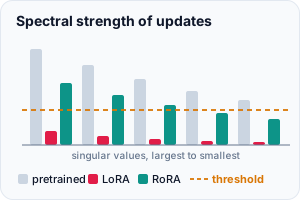
- Why LoRA Fails to Forget: Regularized Low-Rank Adaptation Against Backdoors in Language ModelsIn Findings of the Association for Computational Linguistics (ACL Findings), 2026Key idea Fine-tuning a backdoored model with LoRA on clean data rarely removes the backdoor. We show the cause is spectral rather than just low rank: LoRA updates have singular values far below those of the pretrained weights and align with the wrong directions. RoRA raises spectral strength and corrects the alignment, lowering attack success while keeping clean accuracy.
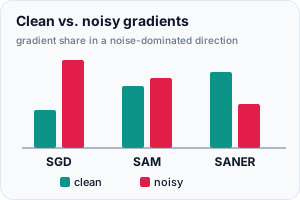
- Understanding SAM’s Robustness to Noisy Labels through Gradient Down-weightingIn International Conference on Artificial Intelligence and Statistics (AISTATS), 2026Key idea Why is SAM robust to noisy labels? Looking at each parameter, when noisy gradients dominate a direction, SAM amplifies the clean gradients more strongly, which down-weights the noisy ones. SANER makes this effect explicit, slowing the memorization of noisy labels and beating both SAM and SGD. It also plugs into other SAM variants.
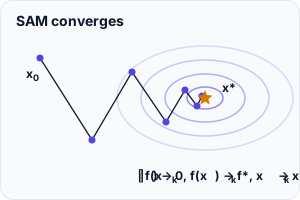
- Fundamental Convergence Analysis of Sharpness-Aware MinimizationIn Advances in Neural Information Processing Systems (NeurIPS), 2024Key idea SAM is widely used, but its basic convergence was not fully understood. We prove that the gradients go to zero, the function values reach the optimal value, and the iterates converge to a solution. Because the proof uses an inexact gradient descent framework, it also covers VaSSO, RSAM and USAM.




Preprints & Under Review
- Preprint
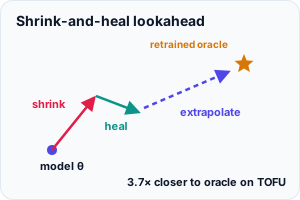 Unlearning by Extrapolating a Shrink-and-Heal Lookahead2026Under reviewKey idea Machine unlearning should make a fine-tuned LLM forget a specific subset of its training data while keeping everything else. Our method takes a short shrink-and-heal lookahead step and extrapolates along it. On TOFU (Llama models up to 8B) it lands 3.7x closer to the retrained oracle than the next-best of 11 baselines, and it stays stable under relearning attacks.
- Preprint
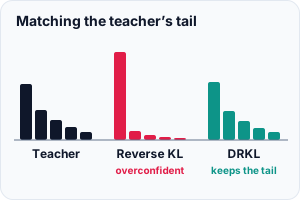 Diversity-Aware Reverse Kullback-Leibler Divergence for Large Language Model Distillation2026Under reviewKey idea Reverse KL is the go-to objective for LLM distillation, but its gradients keep pushing the target-token logit up even after the student already matches the teacher. This makes students overconfident and less diverse, with weak supervision on tail tokens. DRKL removes the effect and strengthens non-target supervision, beating forward KL, reverse KL and recent objectives on Qwen3, Llama-3.2 and OPT with a better fidelity-diversity trade-off.
- Preprint
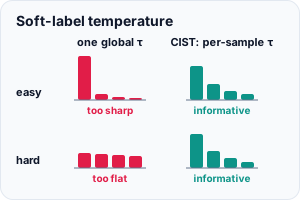 Consistently Informative Soft-Label Temperature for Knowledge Distillation2026Under reviewKey idea A single global temperature makes some teacher soft labels too sharp and others too flat, and it forces teacher and student onto the same logit scale. CIST gives the teacher and the student their own temperature for each sample, guided by the finding that soft-label entropy is governed by the ratio of the max logit to the temperature. It gains up to +3.6% over standard KD on CIFAR-100 at negligible extra cost.
